Schedule Explorer
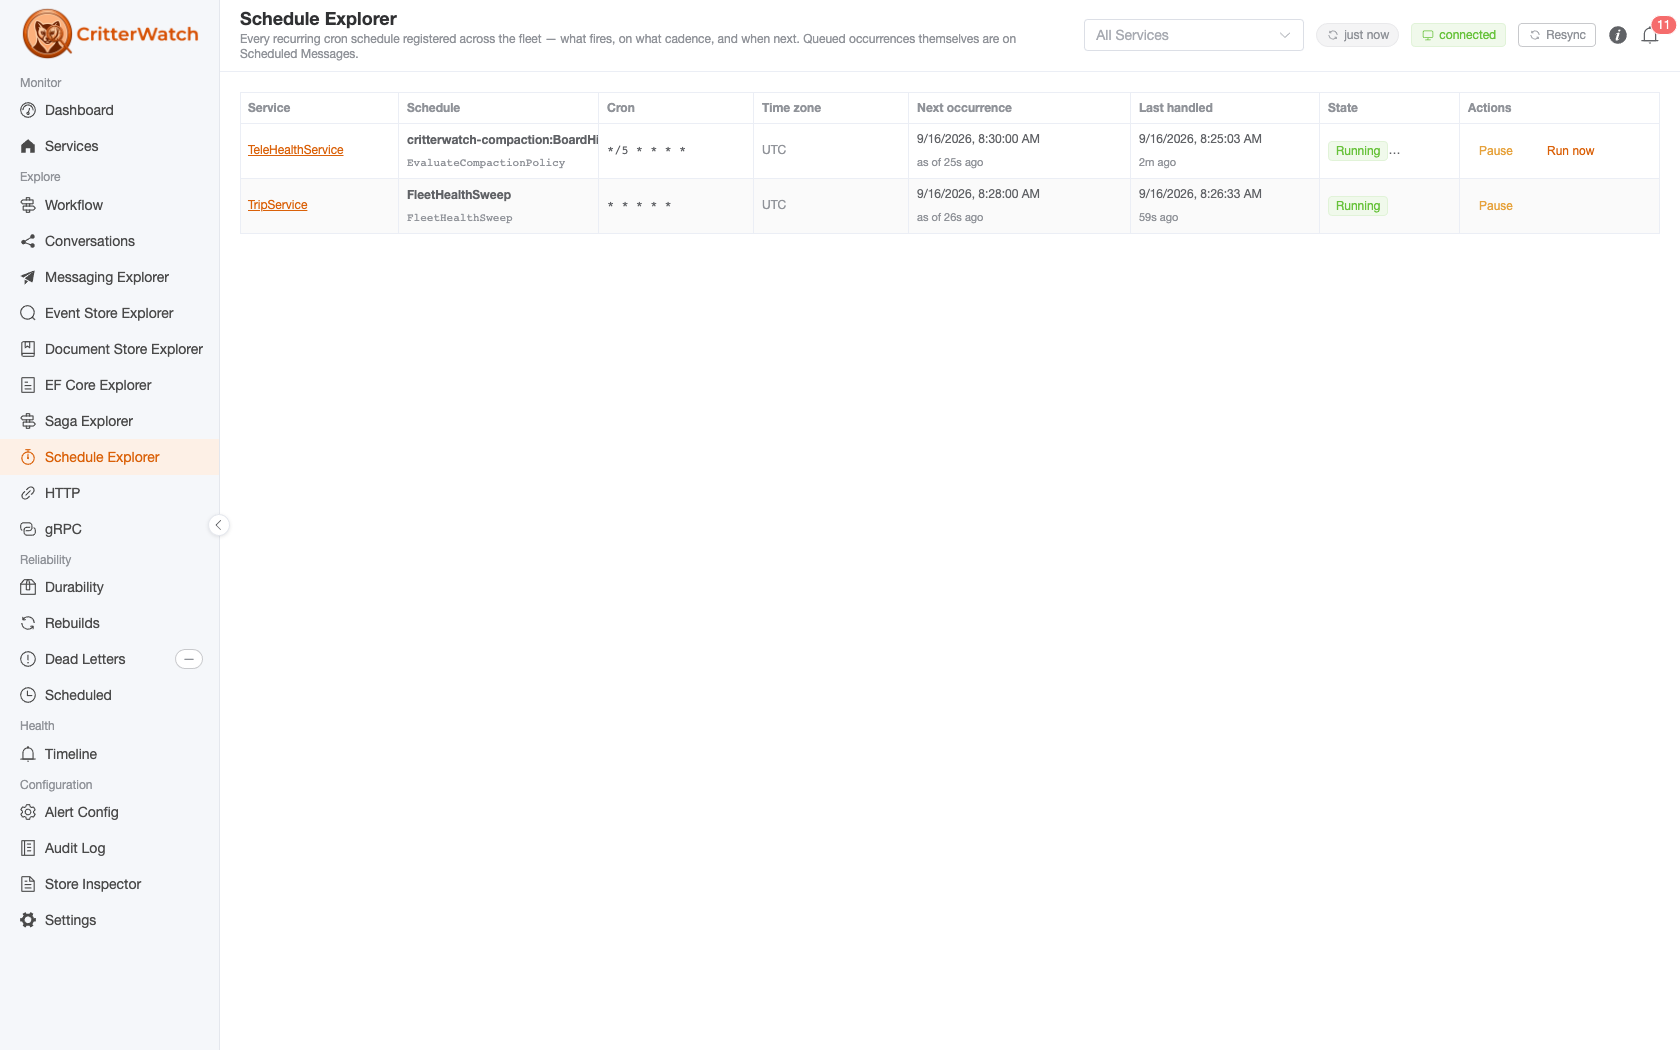
The Schedule Explorer is a fleet-wide catalog of the recurring cron schedules your services register through Wolverine 6.34's opts.Schedules.ScheduleRecurring<T>(...). One row per schedule per service: what fires, on what cron, in which time zone, and when it is next due.
Reach it from Explore → Schedule Explorer (/schedules). The global service selector in the header scopes it, and the scope rides the URL, so /schedules?service=TripService is a shareable deep link. Services that register no schedules never appear — which, for a fleet on anything older than Wolverine 6.34, is all of them.
Schedules, not their firings
This is not the Scheduled Messages page
The two pages answer different questions and it is worth knowing which one you want.
- Schedule Explorer — the schedule: "a
FleetHealthSweepruns every night at 02:00 Chicago time, and next fires at 02:00 tomorrow." - Scheduled Messages — the occurrences queued right now: the actual envelopes sitting in a service's durable inbox waiting to be delivered.
A schedule's pending next occurrence is an ordinary durable inbox row, so it has always been visible on the Scheduled Messages page — and cancellable and reschedulable there. What had no surface at all until #1204 was the schedule itself. Cancelling one occurrence on that page does not stop the schedule; the next occurrence is computed and queued as normal.
The grid
| Column | Description |
|---|---|
| Service | The service that registered the schedule. Links to its detail page. |
| Schedule | The schedule's name, with the message type it publishes underneath |
| Cron | The cron expression. Hover for the time zone occurrences are computed in |
| Time zone | The TimeZoneId the cron expression is evaluated against |
| Next occurrence | When the schedule next fires, with the instant that reading was true underneath |
| Last handled | When a monitored node last actually ran an occurrence — see below |
| State | Running, Paused, or Never fires |
| Actions | Pause / Resume, and Trigger now on a running schedule |
Every runtime reading says when it was true
Underneath the next occurrence is one of three lines, and they are different claims:
| Line | What it means |
|---|---|
as of 40s ago | A live read of the service's own recurring tracking state. Its age is the age of the truth. |
announced 6h ago | The capability announcement's frozen copy. This service does not report live schedule state, so the age says nothing about the schedule — only how long ago the service registered. |
freshness unknown | The service reported no instant at all. There is no way to tell how old the values are. |
The distinction exists because the two used to be indistinguishable, and that cost a real diagnosis: a console showed a next occurrence four minutes in the past beside a schedule that was durably paused, with nothing on screen to suggest either number was old.
Why the announcement cannot carry it: a service re-announces its capabilities when their content hash changes, and the hash covers a schedule's definition fields only — name, cron expression, time zone, message type. The runtime fields ride along but do not contribute to the hash, because NextOccurrence advances on every cron tick: folding it in would turn a change-detection hash into a re-announce firehose, one full capability announcement per tick per service. So the announced copy is frozen at registration time and never catches up.
Instead each service pushes a small live read of its recurring tracking state on its own telemetry cadence, and a pause or resume you perform from this page is reconciled immediately from the service's acknowledgement. A service older than this console's release sends neither, which is exactly what the announced wording is there to tell you.
"Last handled" answers "is it still firing?"
This is the instant a monitored node last ran an occurrence of the schedule — an observed run, not the schedule's own bookkeeping. The two part company precisely when something is wrong: a schedule whose message has no subscribers keeps a moving next occurrence and never handles anything, and a service in an agentless durability mode has an announced schedule that is completely inert.
Empty is not the same as idle
An occurrence is handled wherever its message routed. If that is a different service, or a node whose report has not landed yet, or it happened before this console started watching, the column reads no data — which means not observed from here, never "this schedule is not firing".
It is also the handler's own clock, not the scheduled instant.
Pause and resume
Pause stops a schedule from firing without removing it; Resume starts it again. Both are relayed to the owning service, which applies them to its live recurring agent and acknowledges the result — the row shows a pending spinner until that acknowledgement lands, and every refusal path answers on the same channel, so a refused command never leaves a row spinning.
A pause is only as durable as the service's tracking store
A service with the recurring tracking table records the pause durably and it survives a restart. A service without one applies the pause to its in-memory agent only: it is real, and it takes effect, but a redeploy or restart quietly undoes it.
The console does not present these as the same thing. The service reports which it did, and a non-durable pause is confirmed with an explicit warning saying so rather than a bare success.
Resuming does not backfill. Occurrences that would have fired while the schedule was paused are skipped, not replayed — the same rule Wolverine applies to occurrences missed while a service is down.
Per-schedule pause is not the same as pausing the agent. Wolverine's agent-level pause stops every schedule on the service at once; the actions here target one schedule.
Trigger now
Trigger now runs a schedule once, now, without changing its cron cadence or its next scheduled occurrence. It needs Wolverine 6.38 or later on the monitored service.
- The run starts on the service's next recurring tick, not the moment the console confirms. The request is recorded on the schedule's tracking row, and the recurring agent publishes the run — on whichever node holds the agent, so it works in a cluster.
- It is not a second copy of a scheduled firing. The manual run carries its own deduplication id, so it never collapses into, or doubles, the occurrence the cron will fire anyway.
- Two triggers before the next tick are one run. Pressing it twice quickly does not run the work twice.
- A paused schedule refuses it. Resume first. This is also how to catch up work a pause skipped: resume, then trigger.
- A service with no recurring tracking table records the request on its in-memory agent only, and the console says so, as it does for a non-durable pause.
A compaction policy's row keeps its own Run now instead, which reports the dry-run answer.
Never fires
A schedule reads Never fires when its service runs in the Serverless or MediatorOnly durability mode and has durable message storage configured. Wolverine starts no agents in those modes, so the schedule is registered, announced, and completely inert. It is a misconfiguration, and showing it as Running would be the most misleading thing the page could do.
A service in one of those modes with no message store at all is not flagged: Wolverine starts the recurring agent directly, in memory, for a storeless host, so those schedules genuinely do fire.
What you cannot do from here
One omission is deliberate rather than unfinished:
- Authoring or editing a schedule. Schedules are code-first, and Wolverine exposes no API to add one or re-crontab one on a running host. A button here would have nothing to call — change the registration and redeploy.
Multi-tenancy
Recurring schedules live on the main database only — never per tenant, and never in an ancillary store, including in a modular monolith. A multi-tenant service has one set of schedules for the whole service, and this page renders them as exactly that.
For agents (MCP)
The same surface is available over MCP: list_recurring_schedules to read them, and pause_recurring_schedule / resume_recurring_schedule / trigger_recurring_schedule to act, gated by the recurring-schedule.pause, recurring-schedule.resume and recurring-schedule.trigger capabilities. See the MCP tool catalog.